

The Government That Ships Like a Startup: Enterprise GitOps on AWS
How a large government enterprise deployed a zero-touch, identity-first GitOps platform on AWS, and what every enterprise CTO should take from it.


How a large government enterprise deployed a zero-touch, identity-first GitOps platform on AWS, and what every enterprise CTO should take from it.
TL;DR: Scaling Kubernetes across multiple AWS accounts often leads to security and compliance gaps. This deep dive explains how to build a centralized, zero-touch GitOps platform using AWS EKS, AWS EventBridge, and Kargo to ensure 100% auditable deployments without slowing down developers.
Imagine your organization deploys software to dozens of Kubernetes clusters across twenty AWS accounts. Now imagine that no one, from the CIO and the security team down to the platform engineers, can tell you with certainty what version is running in production right now, who approved the last change, or whether it followed the correct process.
This scenario is not a hypothetical case study. It was the actual reality facing one of the country's most critical government institutions before this project began.
Large government organizations are not startups, and they cannot afford to move fast and break things. Yet, the absence of a centralized delivery platform meant that development teams were doing exactly that. They shipped independently, inconsistently, and without an auditable trail. The compliance team faced constant risks while developers struggled with manual friction every day.
True growth and efficiency do not happen inside the comfort zone. Real value is created when you are willing to challenge the status quo, rethink existing frameworks, and push your infrastructure forward.
What follows is the architecture behind the platform that changed everything, along with an honest account of the three engineering decisions that made it possible.
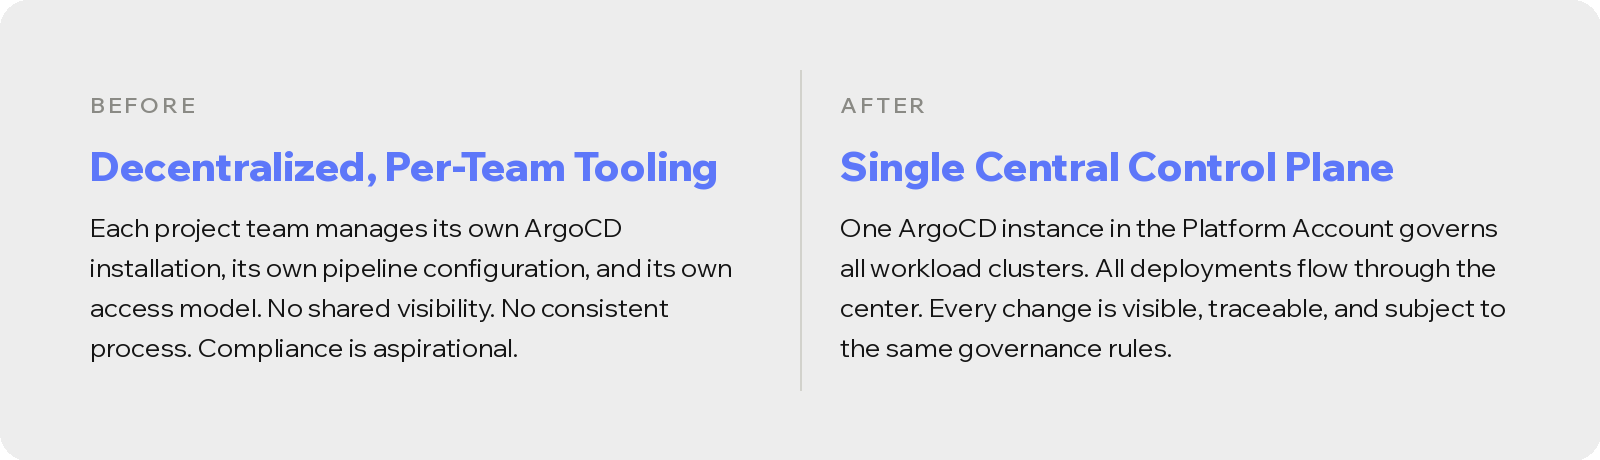
Before the transformation, the engineering organization operated like most large enterprises that have grown faster than their governance. Each project team managed its own deployment tooling, Kubernetes access, and pipeline configuration. On the surface, this setup looked like autonomy, but in practice, it was pure fragmentation.
When a new EKS cluster needed to be connected to a deployment pipeline, the infrastructure team had to field a ticket. That ticket sat in a queue until a senior engineer eventually worked through a manual checklist to create access entries, configure credentials, register the cluster, and scaffold the GitOps repository. Days passed, sometimes even a week, and the developer waiting on the other end had already moved on to something else.
More critically, there was no enforced gate before production. A motivated developer with the right access could theoretically bypass staging entirely. This did not happen because of bad intentions, but because the platform simply had no mechanism to prevent it. For a government agency subject to strict audit requirements, this was a massive liability.
The absence of a centralized platform does not give teams freedom. It gives them exposure to compliance failures, security gaps, and the compounding cost of duplicated effort across the organization.
Three core problems drove the transformation, and they will be familiar to any CTO who has scaled an engineering organization past fifty people:
The solution begins with a single, non-negotiable architectural choice: a central ArgoCD control plane hosted in a dedicated AWS account that manages every workload cluster in the organization.
There is no ArgoCD installed on individual project clusters, and there never will be. Every deployment across every environment and every project is driven from the center. This is a governance philosophy encoded into the infrastructure itself.
ArgoCD is deployed on the management cluster using the AWS EKS Managed Capability, a feature that changes the operational calculus for any organization running GitOps at scale. Instead of managing an ArgoCD Helm installation, patching it, handling upgrades, and worrying about availability, AWS assumes operational responsibility for the control plane. High availability, patching, and scaling become AWS’s responsibility.
For a platform team that previously spent cycles maintaining deployment infrastructure rather than improving it, this shift is material. The team can now focus entirely on the patterns and policies that make the platform valuable, rather than just keeping the lights on.
The most operationally transformative decision in the entire architecture is also the least visible to developers. They never see it happen, and that is precisely the point.
Under the new architecture, a project team provisions its EKS workload cluster using its own Terraform pipeline, which fits into its existing workflow. Terraform writes two parameters to AWS Systems Manager Parameter Store: the cluster ARN and its environment tags. That is the entire developer interaction with the onboarding process, and everything else is automatic.
The elegance of this design is in its scalability. When a new AWS account is added to the organization, it automatically inherits the ability to trigger the onboarding flow because the platform event bus accepts events from any account matching the org-level policy. There is no list to update and no configuration to change. The system is self-extending.
A process that used to take days of manual ticketing now completes in seconds. This is a completely different category of operation.
Historically, connecting a central ArgoCD to remote Kubernetes clusters meant either passing around kubeconfig files, which are sensitive and difficult to rotate, or creating static service account tokens, which are a security audit's worst nightmare. This platform eliminates both approaches entirely.
ArgoCD identifies each target cluster by its AWS EKS Cluster ARN. Authentication is handled through EKS Access Entries, a mechanism that registers the ArgoCD Capability's IAM Role on each workload cluster. When ArgoCD needs to deploy to a workload environment, it presents its IAM identity. The Access Entry on the remote cluster recognizes it and grants precisely scoped access.
No files change hands, no tokens are created, and no secrets can be leaked because there are none to leak. This is what identity-first security looks like in practice. The authentication mechanism is the same one that governs all AWS access, meaning it rotates automatically, is audited in CloudTrail, and cannot be accidentally committed to a Git repository.
The human access model follows the same philosophy. Every developer, DevOps engineer, and manager logs in to ArgoCD via AWS IAM Identity Center (SSO), which is federated with the organization's existing Azure Active Directory. There are no local ArgoCD passwords and no API tokens for user access. If a user's AD account is deprovisioned, their platform access is removed simultaneously.
Multi-tenancy is enforced via ArgoCD AppProjects, which are automatically generated during the onboarding Lambda run. Each AppProject explicitly restricts a team's deployments to their own Git repositories and their designated clusters. A developer logging into the platform sees only their applications, meaning they cannot see, touch, or accidentally affect another team's workloads.
Every platform eventually faces an organizational tension where the engineering team wants to move fast, and the compliance team wants a provable audit trail. Most organizations resolve this with processes, checklists, and change management tickets, but processes can be circumvented. This platform resolves the tension with architecture.
Kargo is the automated promotion engine that sits between a new container image and the environment it will run in. It continuously monitors the organization's Elastic Container Registry for new verified images and drives every promotion decision according to a structured pipeline with exactly one production gate.
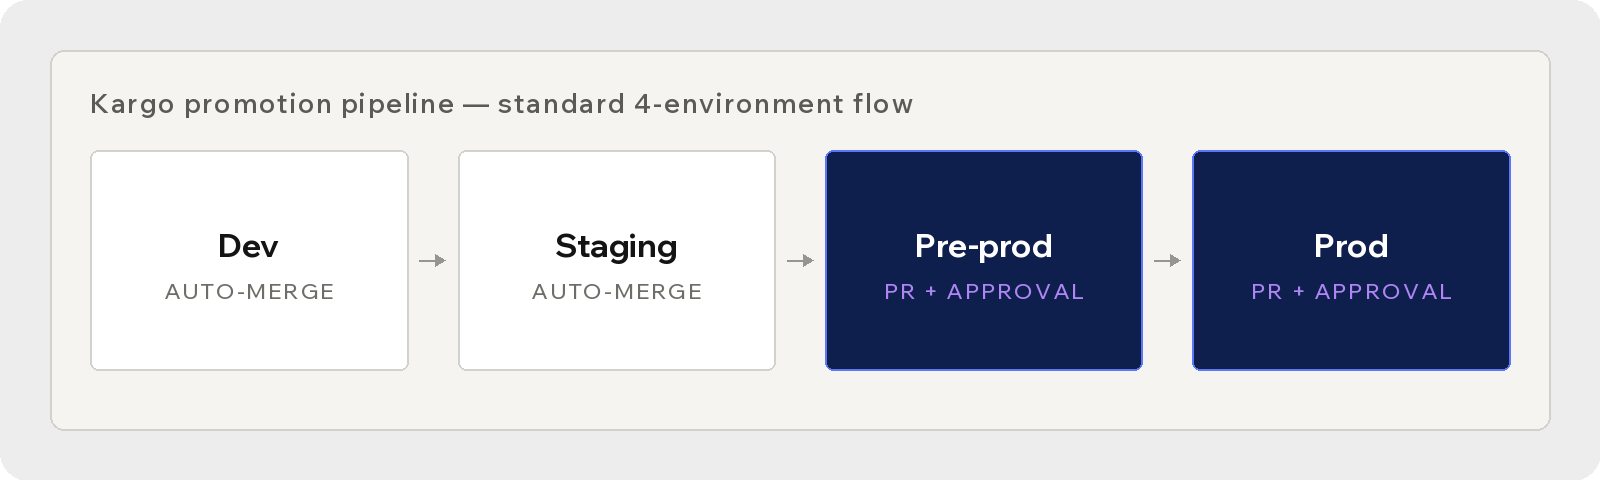
Kargo Promotion Pipeline Standard Flow
For Dev and Staging, Kargo operates fully automatically. When a new image clears ECR, Kargo updates the relevant values. YAML file in the GitOps repository and commits the change. ArgoCD detects the commit and syncs the cluster. The entire flow requires no human involvement.
Production and Pre-production are different. When Kargo determines that an image is ready to promote to these environments, it opens a Pull Request in GitLab that requires manual approval from a designated tech lead or release manager before it can be merged. Only after the merge does ArgoCD pick up the change and deploy it.
This production gate is enforced at the architecture level, not the policy level. Developers have read-only access to production inside the ArgoCD UI, and their role does not permit a direct sync. The only path to production is through the Kargo pipeline and the mandatory human approval in GitLab.
Governance enforced by policy can be bypassed under pressure. Governance encoded into architecture is governance that holds during an audit, at 2:00 AM, and on days when teams are moving fast.
The platform's Git structure reflects its governance philosophy at every level. There are two categories of repositories, and the boundary between them is enforced absolutely.
The Platform Repository is owned exclusively by the platform team. It contains the root ArgoCD application, all AppProject definitions, and all ApplicationSets. Developers have no write access, which establishes clear role clarity. The platform team owns the delivery infrastructure, while project teams own what they deliver.
The Per-Project GitOps Repository is created automatically by the Registration Lambda during onboarding. It contains one folder per environment, each with its own values. YAML file holding the image tag and environment-specific configuration. Kargo writes to this file during promotion. Developers can write to the Dev and Staging folders, but the Production and Pre-production folders are protected branches requiring a Pull Request. The architecture makes it structurally impossible to directly modify what runs in production.
Every state change in every environment is a Git commit with a timestamp, an author, and a pull request thread. When a compliance team needs to demonstrate what was running in production on a specific date and who approved it, the answer is a single git log command. This delivers a provable, immutable record without needing to cross-reference multiple tools.
Platform engineering projects are often measured by technical metrics such as deployment frequency and lead time. These matter, but for a C-level audience, the more important question is how the organization operates.
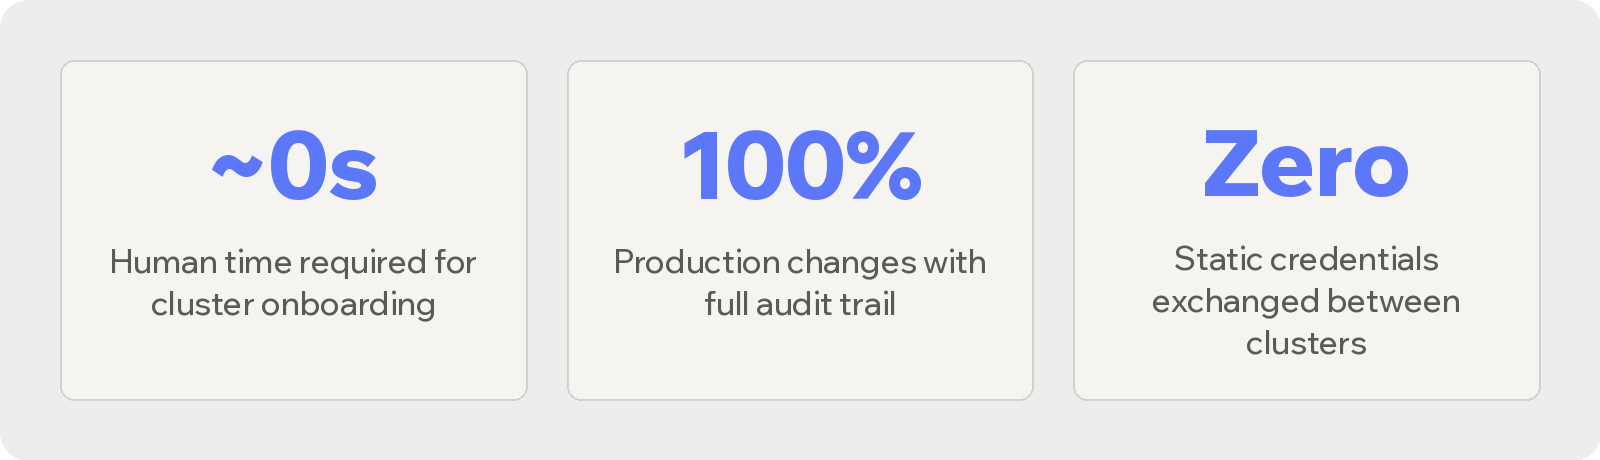
Three key things changed about the operational reality:
The future of enterprise cloud delivery is not about making every developer a Kubernetes expert, nor is it about adding more documentation. It is about building a platform that makes the right thing the easy thing, where deploying safely is the natural path.
AWS EventBridge cross-account eventing, EKS Managed Capabilities for ArgoCD, and Kargo's GitOps promotion pipelines serve as three components of a single architectural answer to a critical question: how do you give developers speed without giving up control?
The answer is to stop relying on people to follow rules and to start building systems in which the right behavior is the only available behavior. That is how we maximize your cloud infrastructure, and once you build it this way, there is no going back.
It runs ArgoCD as a managed AWS service instead of a self-hosted Helm install. AWS owns high availability, patching, and scaling, so the platform team can focus on policy instead of upkeep.
An org-wide EventBridge rule forwards events to a central bus that accepts any account matching an org-level policy. New accounts inherit the onboarding flow automatically, with no list to update.
Through EKS Access Entries tied to ArgoCD's IAM role, no kubeconfig files or static tokens ever exist. The same identity is auto-rotated and audited in CloudTrail.
Kargo promotes new images through Dev and Staging automatically, but Pre-Prod and Prod require a manual PR approval from a tech lead before ArgoCD deploys. Developers have no direct sync access to production.
Every change is a Git commit with a timestamp, author, and PR thread in the project's GitOps repo. Compliance can reconstruct any deployment's history with a single git log command.
How a large government enterprise deployed a zero-touch, identity-first GitOps platform on AWS, and what every enterprise CTO should take from it.